





ML backend engineer: I build the systems that serve, feed and secure models.
LLM inference servers on consumer GPUs, training-data pipelines, MCP servers and agent backends, in Python and Rust, built end to end.




- 🚀 Run a 120B model at 28 tokens/s on an 8 GB laptop GPU: a llama.cpp extension that keeps hot MoE experts in VRAM, up to 2.1x faster than the best layer split.
- 📈 Raised model accuracy by +8.14 points on average across 15 benchmark runs by cleaning training data, and cut training time by ~49%.
- 🧠 Gave AI coding agents a memory over MCP that answers a question in ~168 tokens instead of reading 38,921 tokens of source (~231x cheaper).
- 🖥️ Built a desktop app for local and cloud models with an approval-gated agent mode and a Rust addon that made audit logging ~60x faster.
- 🔐 Wrote a fail-closed Rust MCP gateway with OIDC, RBAC, signed approval tickets and a tamper-evident audit log.
- 🧪 Measured, tested and documented: I don't claim a number until a benchmark backs it.
🚀 extended-strata-moe: big MoE models on a small GPU
Extends Strata from one model to every Mixture-of-Experts architecture llama.cpp supports (DeepSeek, Qwen3 MoE, gpt-oss, GLM, Llama 4, Kimi and more). The experts a conversation actually uses stay cached in VRAM, the CPU computes the misses from system RAM at the same time, and the two sync through a 3 µs CUDA mailbox, so nothing is uploaded over PCIe during generation.
| RTX 4060 Laptop, 8 GB VRAM | Best llama.cpp layer split | extended-strata-moe |
|---|---|---|
| gpt-oss-120b (63 GB) | 15.9 t/s | 28.2 t/s (+77%) |
| Qwen3-Coder-Next 80B (65.6 GB) | 17.8 t/s | 37.2 t/s (+109%) |
Verified on 53 MoE architectures with KL divergence under 0.002 against CPU-only evaluation. It serves OpenAI- and Anthropic-compatible APIs, so Claude Code or Cursor can use it directly.
C++ / CUDA Python llama.cpp LLM inference
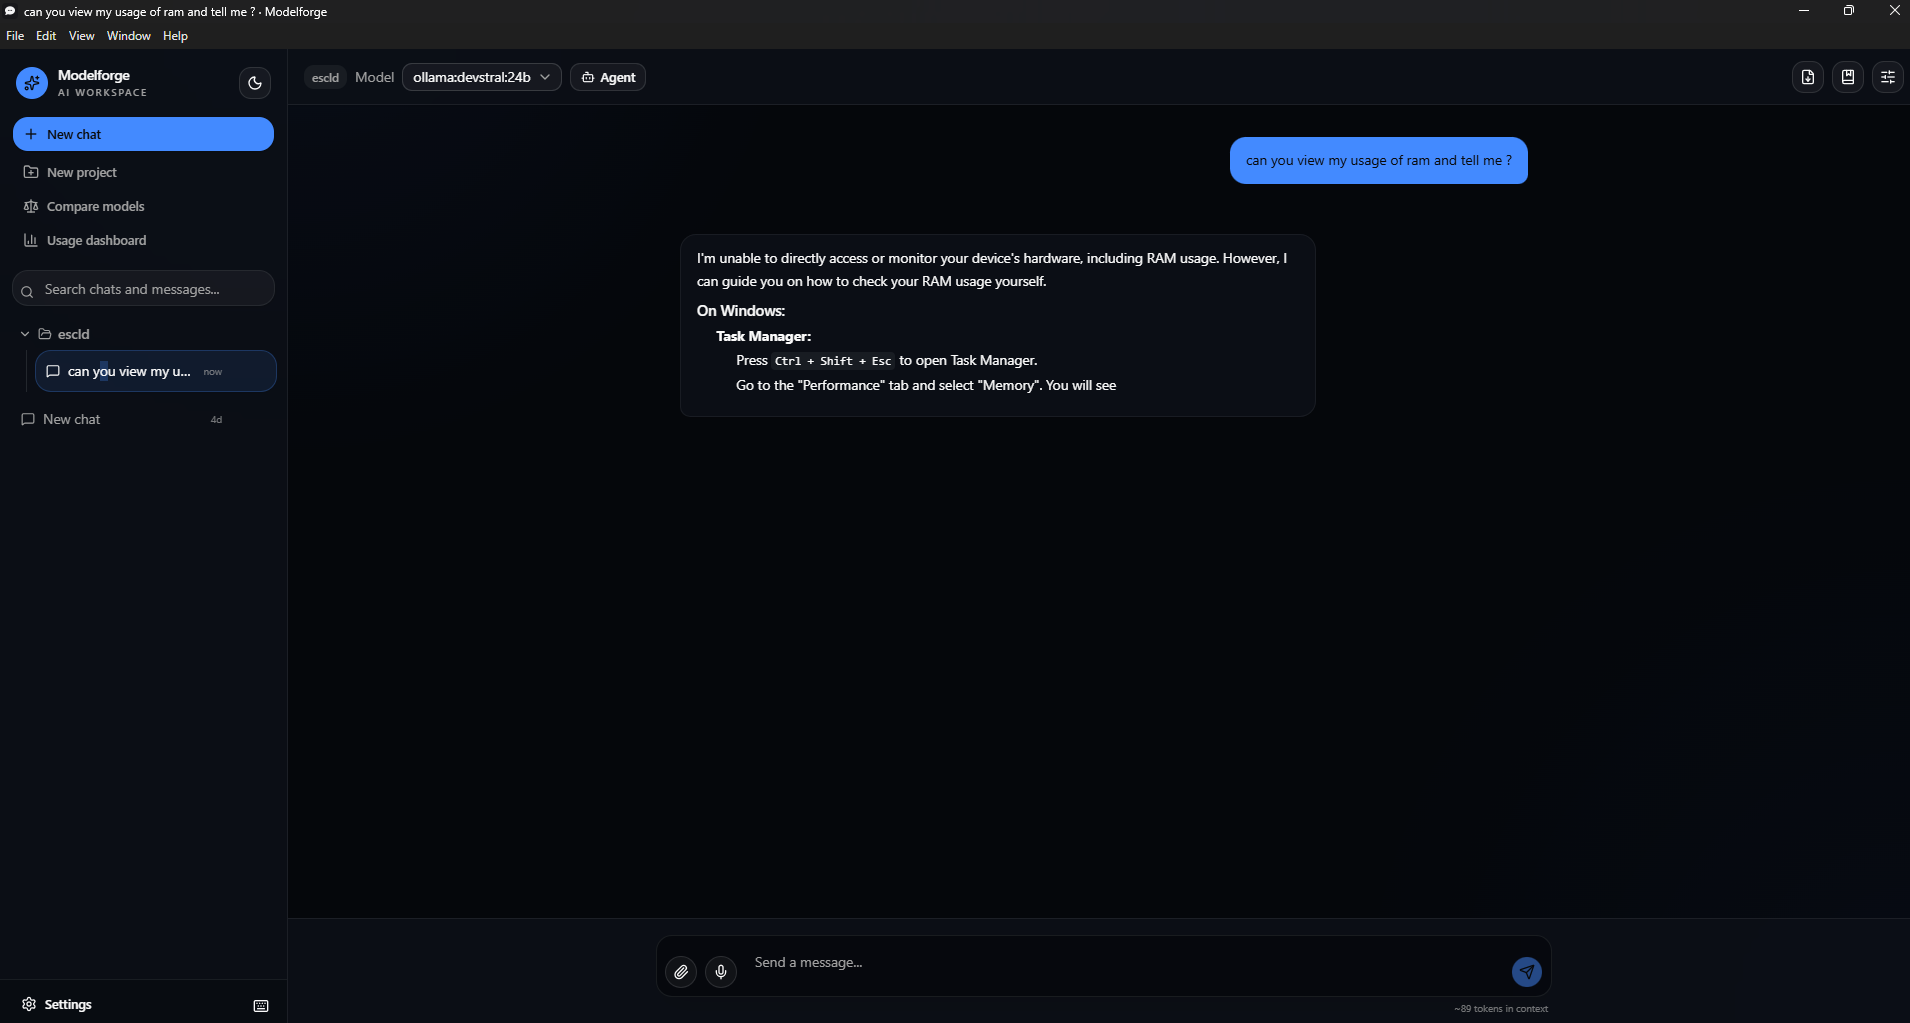
🧠 modelforge: local and cloud AI models in one desktop app
An Electron app that puts local models (llama.cpp, vLLM) and cloud models (OpenAI, Anthropic, Gemini) in one streaming chat, now focused on clinical decision support and research.
- Agent mode with guardrails: the model can read and write files and run commands in a folder you choose, and every action needs your approval.
- Safety by design: emergency red-flag detection, allergy and medication conflict warnings, and a consent preview before patient data goes to a cloud provider.
- Rust where it earns its place: a napi-rs addon cut 5,000 audit-log writes from about 20 s to about 0.3 s, with a TypeScript fallback.
- Honest scope: documented as decision support, not a diagnostician or a certified medical product.
Electron TypeScript Rust (napi-rs) llama.cpp vLLM MCP
📊 buffdata: better training data means better models
A Python CLI and SDK that validates, deduplicates, PII-redacts and LLM-scores datasets before training. It works with OpenAI, Anthropic, Gemini or a local model, and a Rust worker runs managed jobs from a queue.
| Benchmark (40% duplicated, 10% empty rows) | Before | After |
|---|---|---|
| DBpedia-14 | 86.97% | 96.68% |
| Emotion | 71.23% | 83.77% |
| AG News, 100k rows | 83.39% | 89.42% |
| Training time, AG News 100k | 80.2 s | 42.3 s |
On already-clean data, accuracy stays within ±0.10 points, so it doesn't damage good datasets.
Python Rust LLM APIs Data quality
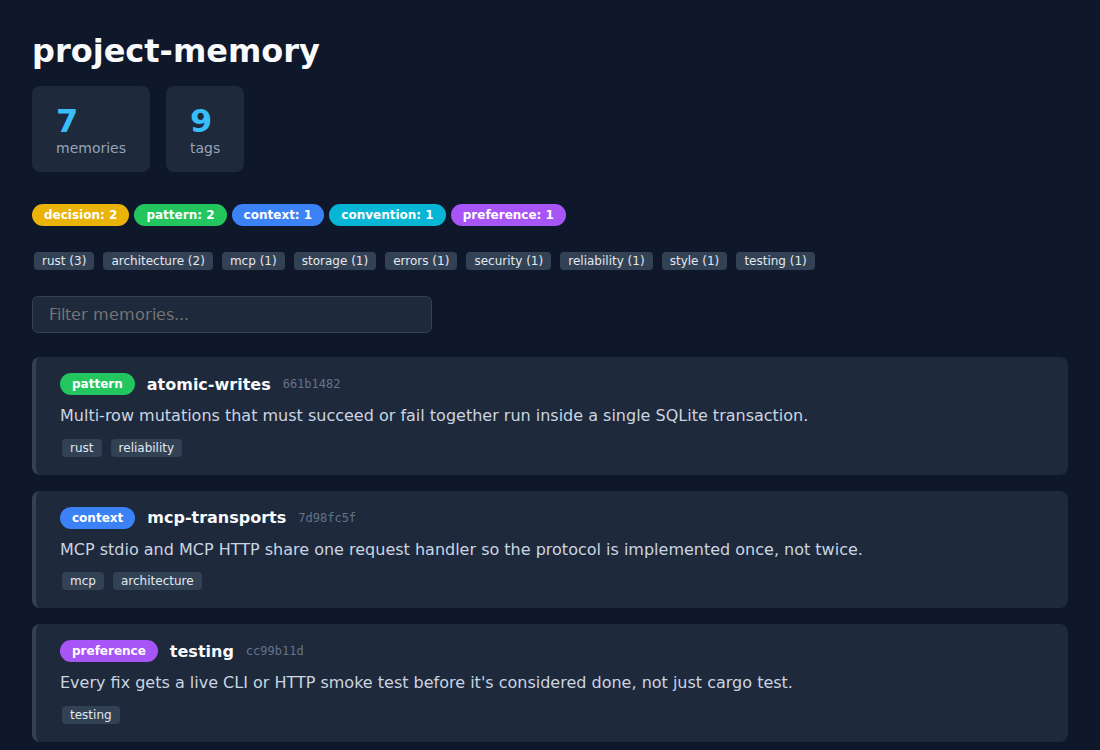
🗂️ project-memory: long-term memory for AI coding agents
pmem stores a project's conventions, decisions and patterns in SQLite and serves them to any MCP client (Claude Code, Cursor, OpenCode), so an agent stops re-reading the codebase every session.
- ~231x cheaper than reading the source: 50 real questions averaged 168 tokens each, and every one found its answer.
- Fuzzy and full-text search, snapshots, duplicate detection, AES-256-GCM encryption and a web dashboard, in a 9.9 MB Rust binary.
Rust MCP SQLite AI agents
🎓 expert-mentor: turn any LLM into a calibrated tutor
A CLI on PyPI that turns Claude, ChatGPT, Gemini or a local Ollama / llama.cpp model into an expert mentor for any field. It writes provider-native prompts, runs the session, remembers what you've mastered and quizzes you with spaced repetition.
pipx install expert-mentorPython Prompt engineering LLM APIs Claude Code skill
🔐 modelforge-clinical-mcp: a security-first MCP gateway for clinical AI
A Rust gateway that decides what an AI model may read or change. It fails closed and enforces OIDC tokens, roles, per-field grants and kill switches. Writes need a signed single-use approval ticket and are deduplicated by an idempotency key, and every decision lands in an audit log without patient data.
Rust MCP OIDC / OAuth 2 Zero trust
I'm self-taught and learned by building real projects instead of tutorials. For every project, I:
- Start with the hard problem. GPU memory scheduling, dataset contamination, agent permissions: the part most people would outsource.
- Measure it. Every number above comes from a benchmark in the repo.
- Make it runnable. One-command setup, CI, releases and docs, so someone else can use it without asking me.
Hiring for a remote ML backend or ML infrastructure role? I'd like to hear about it.
📫 salihyilboga98@gmail.com · 🌐 portfolio.voidstackloop.com