
Comprehensive LLM evaluation at scale - A production-ready framework for evaluating large language models across 90+ benchmarks.


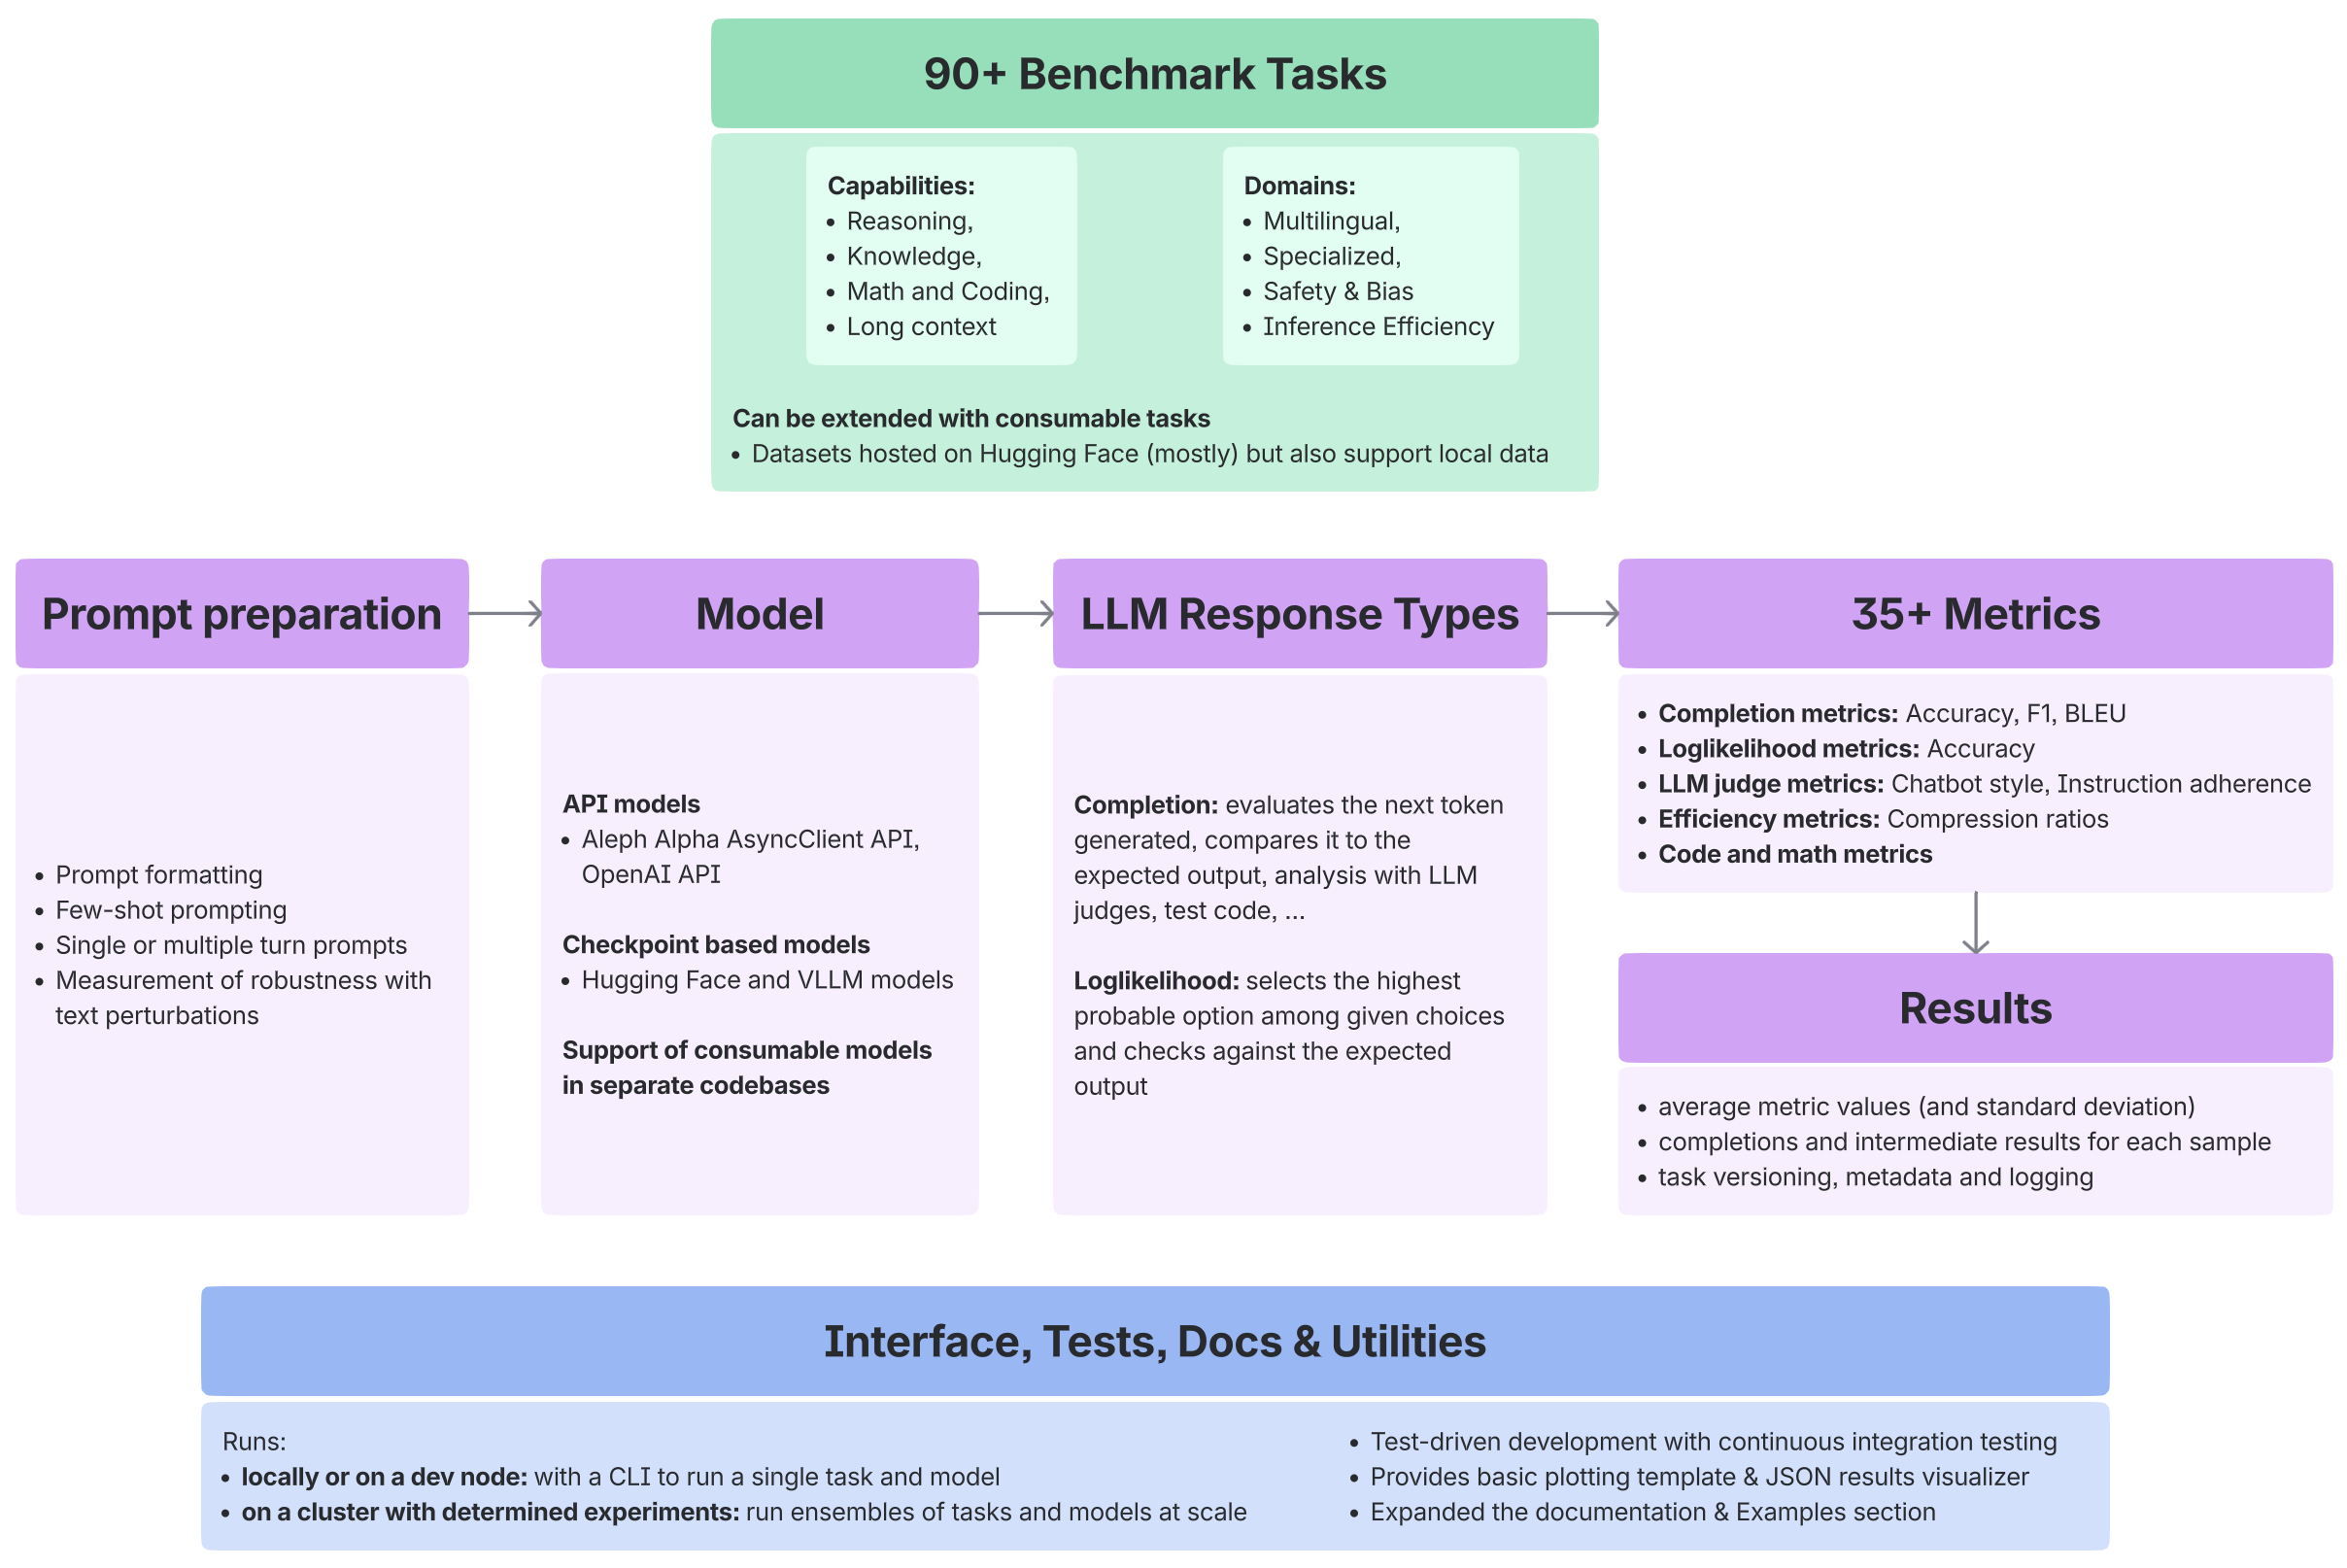
- Scalability: Built for distributed evaluation. Currently providing an integration with Determined AI.
- Extensibility: Easily add custom models, benchmarks, and metrics with object-oriented base classes.
- Comprehensive: Comes pre-loaded with over 90 tasks covering a broad and diverse range, from reasoning and coding to safety and long-context. Also comes with a comprehensive set of metrics, including LLM-as-a-judge evaluations.
- Flexible Model Integration: Supports OpenAI-compatible endpoints or custom implementations using the BaseLLM class.
- Custom Benchmarks: Easily add new benchmarks with minimal code using the BaseTask class.
- Custom Metrics: Easily define new metrics using the BaseMetric class.
- Perturbation Testing: Robustness analysis with configurable perturbation types and probabilities.
- Rich Outputs: Generates JSON results, plots, and detailed analysis reports.
- Statistical Analysis: Includes confidence intervals and significance testing for reliable comparisons.
- Docker Support: Pre-configured Dockerfiles for local and distributed setups.
For full documentation, visit our Docs Page.
The codebase is tested and compatible with Python 3.12. Detailed installation instructions can be found here.
The easiest way to get started is by installing the library via pip and use it as an external dependency.
pip install eval_framework
There are optional extras available to unlock specific features of the library:
determinedfor running jobs via determined.
As a short hand, the all extra installs all of the above.
We use uv to better resolve dependencies when downloading the extras. You can install uv with:
curl -LsSf https://astral.sh/uv/install.sh | shor by follwing the uv installation docs.
Now, you can safely install the project with all optional extras:
uv sync --all-extrasor with pip
uv pip install eval_framework[all]Tip: ensure python is properly installed with uv:
uv python install 3.12 --reinstall
To evaluate a single benchmark locally, you can use the following command. The example below talks to the OpenAI API and needs OPENAI_API_KEY to be set. Any OpenAI-compatible server (for example vLLM) can be targeted by adding base_url=http://host:port/v1 to --llm-args.
eval_framework \
    --llm-name eval_framework.llm.openai.OpenAIModel \
    --llm-args model_name="gpt-4o-mini" \
    --task-name "MMLU" \
    --task-subjects "abstract_algebra" \
    --output-dir ./eval_results \
    --num-fewshot 5 \
    --num-samples 10
For more detailed CLI usage instructions, see the CLI Usage Guide.
Subset of core capabilities benchmarks coverd by eval-framework:
| Reasoning | Knowledge | Math | Coding | Structured outputs | Long Context |
|---|---|---|---|---|---|
| COPA, BalancedCOPA | ARC | AIME | BigCodeBench | IFEval | InfiniteBench |
| Hellaswag | MMLU | GSM8K | HumanEval | StructEval | QUALITY |
| Winogrande | Openbook QA | MATH-500 | MBPP | ZeroSCROLLS |
Subset of language-specific and domain-specific benchmarks coverd by eval-framework:
| Multilingual | Specialized | Safety & Bias | Efficiency Metrics |
|---|---|---|---|
| WMT Translation | MMLU | TruthfulQA | Compression ratios |
| FLORES-200 | Legal (CaseHold) | Winogender | Runtime |
| Multilingual MMLU | Scientific (SciQ) | ||
| German/Finnish tasks |
Tasks focused on logical reasoning, text distillation, instruction following, and output control. Examples include:
- AIME 2024: Logical Reasoning (Math)
- DUC Abstractive: Text Distillation (Extraction)
- Custom Data: Complaint Summarization: Text Distillation (Summarization)
Tasks emphasizing classification, reasoning, and open QA. Examples include:
- Abstract Reasoning Challenge (ARC): Classification
- Casehold: Open QA
Tasks designed for long-context scenarios, including QA, summarization, and aggregation. Examples include:
- InfiniteBench_CodeDebug: Programming
- ZeroSCROLLS GovReport: QA (Government)
Evaluation metrics include:
- Completion Metrics: Accuracy, Bleu, F1, Rouge
- Loglikelihood Metrics: Accuracy Loglikelihood, Probability Mass
- LLM Metrics: Chatbot Style Judge, Instruction Judge
- Efficiency Metrics: Bytes per Sequence Position
For the full list of tasks and metrics, see Detailed Task Table.
Eval-Framework provides a unified interface for evaluating language models across diverse benchmarks. The framework follows this interaction model:
- Define Your Model - Specify which model to evaluate (OpenAI-compatible endpoint or custom)
- Choose Your Task - Select from 150+ available benchmarks or create custom ones
- Configure Evaluation - Set parameters like few-shot examples, sample count, and output format
- Run Evaluation - Execute locally via CLI/script or distribute via Determined AI
- Analyze Results - Review detailed JSON outputs, metrics, and generated reports
- Models: Defined via the
BaseLLMinterface (OpenAI-compatible endpoints, custom APIs); see the Model Arguments guide - Tasks: Inherit from
BaseTask(completion, loglikelihood, or LLM-judge based) - Metrics: Automatic scoring via
BaseMetricclasses - Formatters: Handle prompt construction and model-specific formatting
- Results: Structured outputs with sample-level details and aggregated statistics
- Install the framework (see Quick Start above)
pip install eval_framework
- Create and run your first evaluation against an OpenAI-compatible endpoint (requires
OPENAI_API_KEY; passbase_url=...to the constructor to target a self-hosted server such as vLLM):
from pathlib import Path

from eval_framework.llm.openai import OpenAIModel
from eval_framework.main import main
from eval_framework.tasks.eval_config import EvalConfig


# Define your model
class MyModel(OpenAIModel):
    LLM_NAME = "gpt-4o-mini"


if __name__ == "__main__":
    # Initialize your model
    llm = MyModel()

    # Running evaluation on MMLU abstract algebra task using 5 few-shot examples and 10 samples
    config = EvalConfig(
        output_dir=Path("./eval_results"),
        num_fewshot=5,
        num_samples=10,
        task_name="MMLU",
        task_subjects=["abstract_algebra", "astronomy"],
        llm_class=MyModel,
    )

    # Run evaluation and get results
results = main(llm=llm, config=config)- Review results - Check
./eval_results/for detailed outputs and use our results guide to interpret them
- Use CLI interface: See CLI usage guide for command-line evaluation options
- Understand model arguments: Read out Model Arguments guide
- Create custom benchmarks: Follow our benchmark creation guide
- Scale your evaluations: Use Determined AI integration for distributed evaluation
- Understand your results: Read our results interpretation guide
- Log results in WandB: See how we integrate WandB for metric and lineage tracking
- CLI Usage Guide - Detailed instructions for using the command-line interface
- Understanding Results - How to read and interpret evaluation results
- Understanding Model Arguments - Thorough guide on each constructor argument for salient model classes
- Adding New Benchmarks - Complete guide with practical examples for adding new benchmarks
- Benchmarks and Metrics - Comprehensive overview of all available benchmarks and evaluation metrics
- Overview of Dataloading - Explanation of dataloading and task/sample/message structure
- Using Determined - Guide for distributed evaluation using Determined AI
- Controlling Upload Results - How to manage and control the upload of evaluation results
- Contributing Guide - Guide for contributing to this project
- Testing - Guide for running tests comparable to the CI pipelines
If you use eval-framework in your research, please cite:
@software{eval_framework,
  author={Aleph Alpha Research},
  title={Aleph Alpha Eval Framework},
  year={2026},
  version = {x.y.z},
  url={https://github.com/Aleph-Alpha-Research/eval-framework}
}This project is licensed under the Apache License 2.0.
The constituent tasks' datasets can be subject to specific, more restrictive license terms by third parties. By using eval-framework you agree to adhere to and be bound by such license terms in the individual case.
This project has received funding from the European Union’s Digital Europe Programme under grant agreement No. 101195233 (OpenEuroLLM).
The contents of this publication are the sole responsibility of the OpenEuroLLM consortium and do not necessarily reflect the opinion of the European Union.

